Blog

Latest news and updates from LLM Gateway

A glowing television showing a minimal app dock mounted on the central chip of a dark circuit board, with a remote, a key and a house icon around it, representing an AI agent replacing a Samsung TV home screen

Hack Your Samsung TV: Replace Smart Hub With an AI Agent

How to hack a Samsung Tizen TV so the Home button opens your own Apple TV-style launcher instead of Smart Hub: the sdb and vconf trick that makes it work, what cannot be removed on retail firmware, the $174 and 2,306 model calls it took, and a prompt you can paste into any coding agent with an LLM Gateway key.

By Ismail Ghallou

October 25, 2026
A microchip lifted open on a dark circuit board revealing glowing internal layers, with a magnifying glass, binary digits and a wrench around it, representing AI-assisted reverse engineering with REA

Reverse Engineering With AI: REA Setup When Claude Refuses

A guide to reverse engineering with AI agents using REA (Reverse Engineer Anything): what it inspects, how to set it up with Claude Code, Codex or OpenCode, why Claude Opus 5.5 and ChatGPT now stop mid-analysis, and which Chinese-lab models (DeepSeek V4, Kimi K3.1, GLM-5.2, Qwen3.7) finish the job through one API key.

October 25, 2026
A glowing teal shield on the central chip of a dark circuit board, surrounded by a padlock, a key, a magnifying glass over code, a checklist, a git branch and a radar, representing AI gateway security routines

AI Gateway Security: How We Keep LLM Gateway Secure

AI makes attackers faster, and supply chain attacks on LLM infrastructure keep landing. Here is how we approach AI gateway security at LLM Gateway: the routines that patch advisories, the monthly AI security audit, layered code review, and the real pull requests behind them.

October 23, 2026
A LiteLLM tile glowing red above a litellm==1.107.0 tag, with a dashed arrow to an LLM Gateway tile glowing teal above api.llmgateway.io/v1, and a base_url diff from localhost:4000 to api.llmgateway.io

LiteLLM Compromised Again: Infostealer and RAT in 1.107.0

LiteLLM was compromised again on October 21, 2026: version 1.107.0 on PyPI and the official Docker image shipped an infostealer and a remote access trojan that dumped stored provider keys. Here is what happened, how to check if you are affected, what to rotate, and how to move off a self-hosted LiteLLM proxy in two lines.

October 21, 2026
A glowing database cylinder with a restored heartbeat line on a central chip, surrounded by an open padlock, a stopwatch, a heart monitor and a shield with a checkmark, representing the October 19, 2026 LLM Gateway incident report

Incident Report: LLM Gateway Outage on October 19, 2026

On October 19, 2026, from 18:24 to 19:12 UTC, the LLM Gateway dashboard and API were down and the gateway was partially degraded. This incident report covers what customers saw, the timeline, the root cause, why recovery took as long as it did, and what we are changing.

October 20, 2026
A glowing balance scale on a circuit board weighs task quality against inference cost

Smart Routing Benchmark: Cost and Quality

A live Smart Routing benchmark compares the same prompts across routed and fixed-model requests, including classifier charges, answer checks, and latency. See where routing saved money and where it missed.

September 26, 2026
Glossy circuit board with a glowing balance scale on a central chip weighing stacked coins against ascending tiers, representing LLM cost optimization through model routing

LLM Cost Optimization at $100k a Month

A worked model of LLM cost optimization for a team spending $100k a month: what difficulty-based model routing saves at three traffic mixes, what the classifier costs, and the break-even point. Real catalogue prices, explicit assumptions, and the arithmetic to run on your own numbers.

September 25, 2026
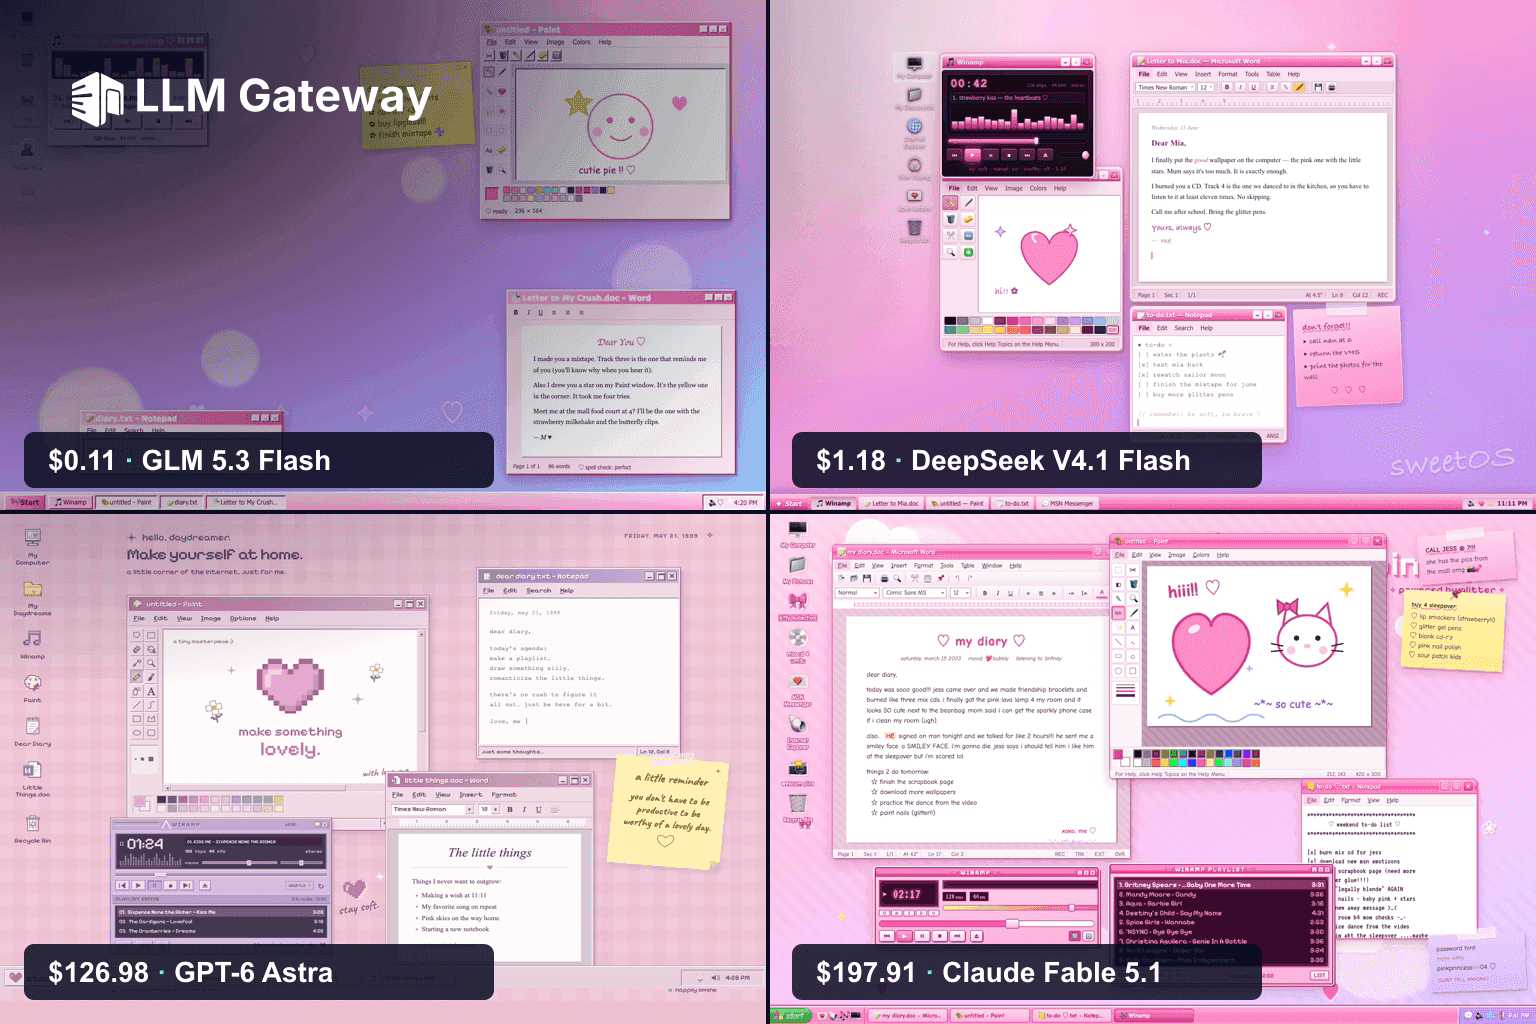
Four pink retro Windows desktops built by different AI models, in a 2x2 grid labelled with what each run cost: $0.11, $1.18, $126.98 and $197.91

Cheap vs Flagship AI Models: $0.10 vs $198

We gave six models the same coding task and measured what each one actually cost. The cheapest produced a working result for 10 cents. The most expensive spent $198 on a single index.html. This AI coding model benchmark shows where the money goes and where it stops buying quality.

September 14, 2026
A glowing boarding-gate arch on a central chip with a lit checklist beside it and light traces leading in from the edge of a circuit board, surrounded by a key, a plug, and a document icon

How to Get Your LLM API Listed on an AI Gateway

A checklist for inference providers who want their LLM API listed on an AI gateway: domain ownership, an OpenAI-compatible endpoint the gateway can actually call, honest capability flags, streaming that reports usage, flat per-million pricing, and rate limits you can sustain. Written against LLM Gateway's Airside listing process.

September 13, 2026
A glowing dispatch radar on a central chip with light traces splitting toward three provider gates on a circuit board, surrounded by a stopwatch, a price tag, and an uptime gauge

How LLM Routing Picks a Provider: A Carrier's Guide

LLM routing on LLM Gateway is an election: every provider listing a model is scored on effective price, uptime, throughput, and latency, and the lowest score wins. This guide explains the scoring from the provider's side, with the fare formula, the uptime penalty, cache-aware pricing, and the levers a carrier controls from Airside.

September 13, 2026
A glowing balance scale weighing coins against a memory-cache module on a circuit board, with light traces routing toward two provider chips

Cache-Aware LLM Routing Learns Your Workload

Cache-aware LLM routing learns cache-hit rates and token proportions from your project's recent model usage, so provider selection reflects the workload you actually run. Available automatically across plans, with explicit per-project overrides on Enterprise.

September 5, 2026
A circuit board with a glowing doorway on the central chip, representing a drop-in Vercel AI Gateway alternative for the AI SDK

A Vercel AI Gateway Alternative Without the Rewrite

Switching off the Vercel AI Gateway used to mean rewriting how your AI SDK app resolves models — and losing provider-native web search on the way out. LLM Gateway now implements the AI SDK's own gateway protocol, so the migration is one line and your bare model strings keep working.

August 12, 2026
A circuit board with a glowing stopwatch on the central chip surrounded by a podium and rising bar chart, representing AI gateway latency benchmarks

Ranked #1 on an Independent AI Gateway Benchmark

In the August 7 run of computesdk's independent AI gateway benchmark, LLM Gateway ranked first of six gateways with a composite score of 90.8 — driven by the tightest tail latency in the field, not the fastest median. Here's what the benchmark measures, what our numbers actually show, and how to run it yourself.

August 8, 2026
Glossy circuit board with a glowing stopwatch on the central chip and light traces racing toward it, representing an AI gateway latency benchmark

OpenRouter vs Vercel vs LLMGateway Performance

We measured AI gateway performance with an open-source TTFT benchmark: 75 cold + 75 warm interleaved runs of claude-haiku-4.5 against LLM Gateway and OpenRouter, with phase-by-phase timings and raw data published. LLM Gateway reached first token ~35% faster cold and ~34% faster warm, and here is exactly how to reproduce the numbers.

July 22, 2026